

Table of contents


How to test AI agents effectively (5 tips)

Jon Gitlin
Since AI agents rely on large language models (LLMs) that can hallucinate or misinterpret instructions, they can take harmful actions—from sharing Social Security numbers with unauthorized individuals to creating tickets with inaccurate or misleading context.
To help prevent any harmful agentic actions, you can test each agent rigorously.
We’ll show you how through several best practices, but first, let’s align on a definition for testing AI agents
What is AI agent testing?
AI agent testing is the process of evaluating an agent’s behavior across inputs to verify that it selects the right tools and generates outputs that meet predefined expectations or performance metrics.
Related: Overview on authenticating AI agents
Best practices for testing AI agents
We’ll break down a few measures you can follow and how Merge Agent Handler’s Evaluation Suite can support each.
Measure your agents’ hit rates across tools
Hit rate is the percentage of time that an agent calls a specific tool when it needs to.
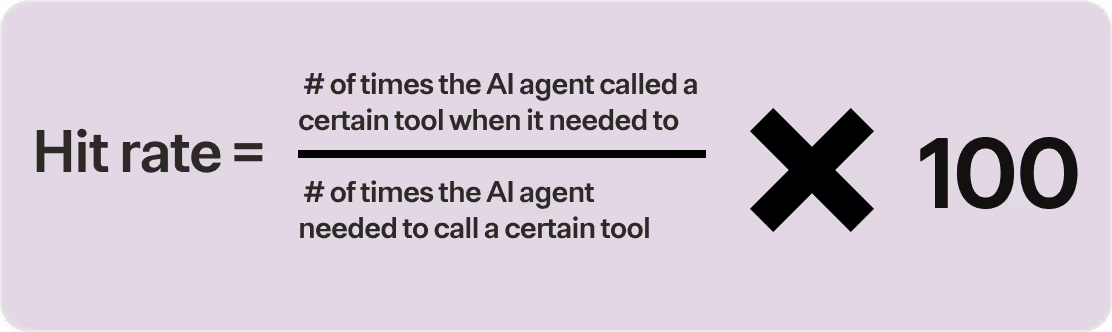
To measure this, you can define a wide range of scenarios for calling a specific tool. For example, a reference scenarios for creating a Jira issue can look as follows:
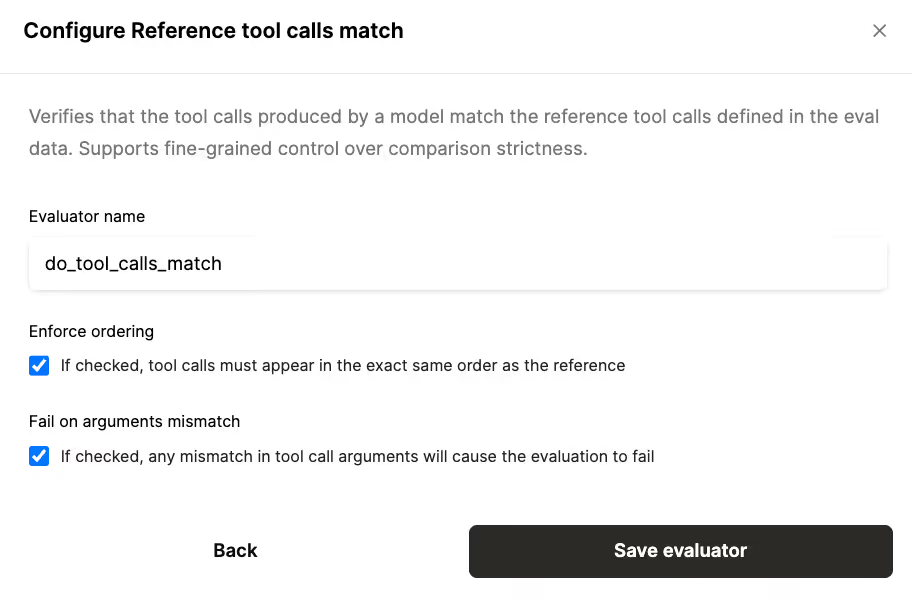
You can also determine how precise you want to be when assessing the test tool calls. For example, if your test output precisely matches this tool call, your hit rate is successful. But if the text match isn’t entirely the same (e.g., minor variations in wording), you may still want it to fail—even if the outputs still have the same semantic meaning.
Related: Best practices for observing MCP servers
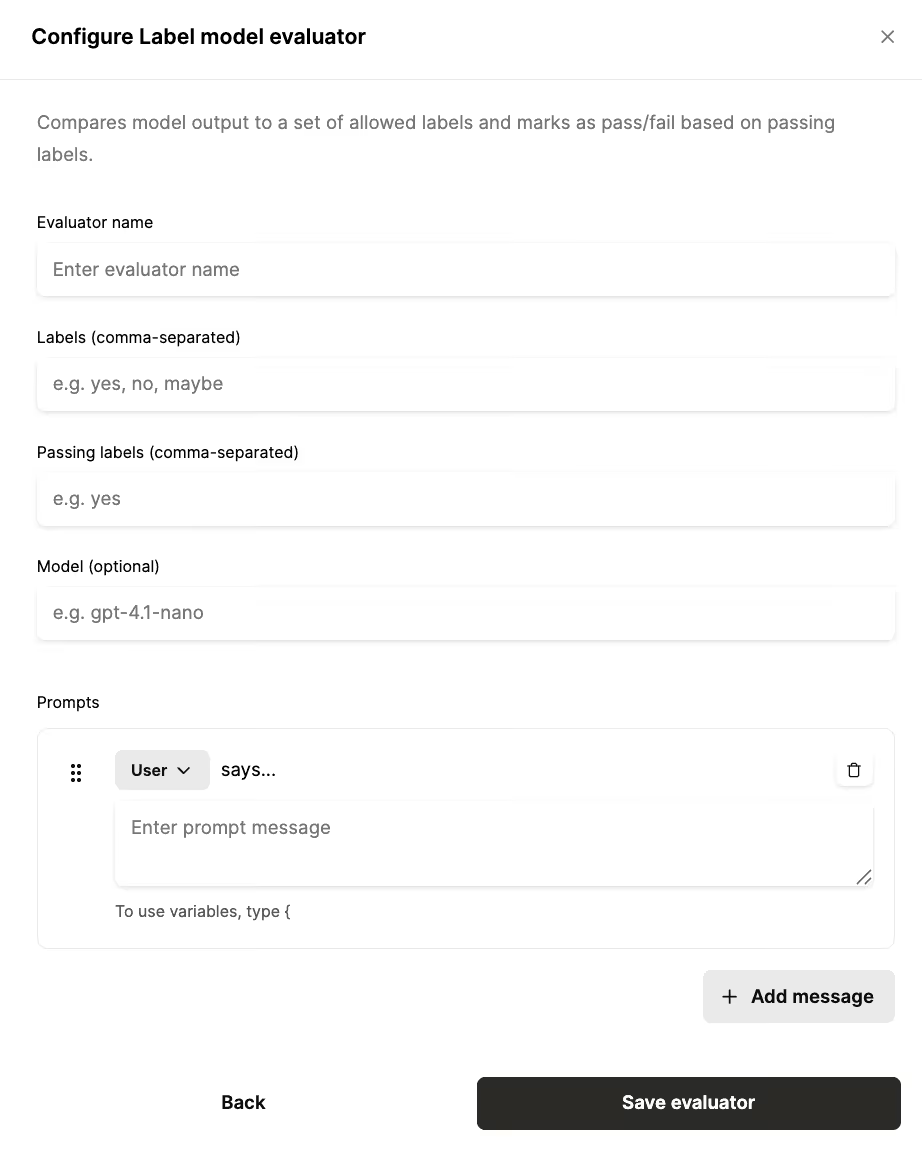
Set up pass/fail checks on your agents’ test outputs
To quickly determine whether an agent produces the correct outputs for any prompt, you can set up a test where you:
- Use a specific prompt(s)
- Add labels for all the potential outputs
- Mark a certain label(s) as passing and the rest as failing
For instance, you can use a prompt like “The website is down. Should we create a Jira issue that’s marked as 'High Priority?'” and the labels can include “Yes” or “No.”
In this case, “Yes” is a passing label, as the website going down is clearly a high priority issue.
Related: Best practices for managing your AI agents
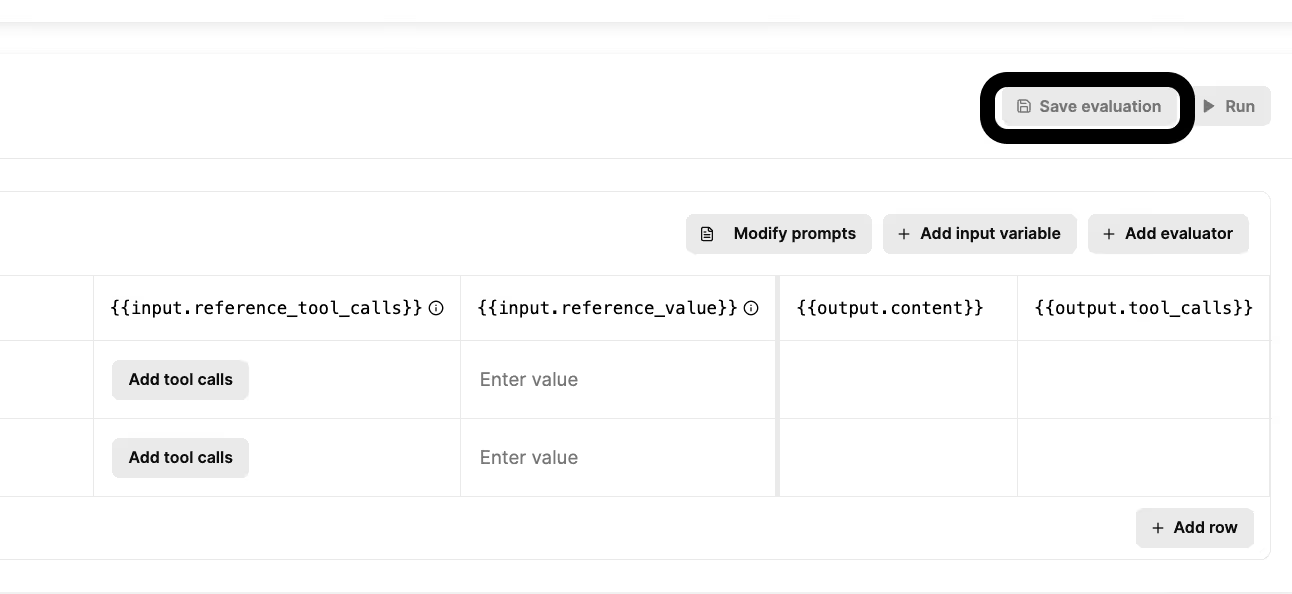
Re-run every test when your agents’ underlying models change
LLMs can vary significantly from one another, and these differences can translate to meaningful changes on your agents’ behaviors. For example, a newer model might phrase tool arguments differently or interpret instructions more loosely than before.
To ensure the model changes aren’t changing your agents in undesirable ways—and to course correct quickly if they do—you can re-run all of your existing tests.
Test every LLM your agents might use
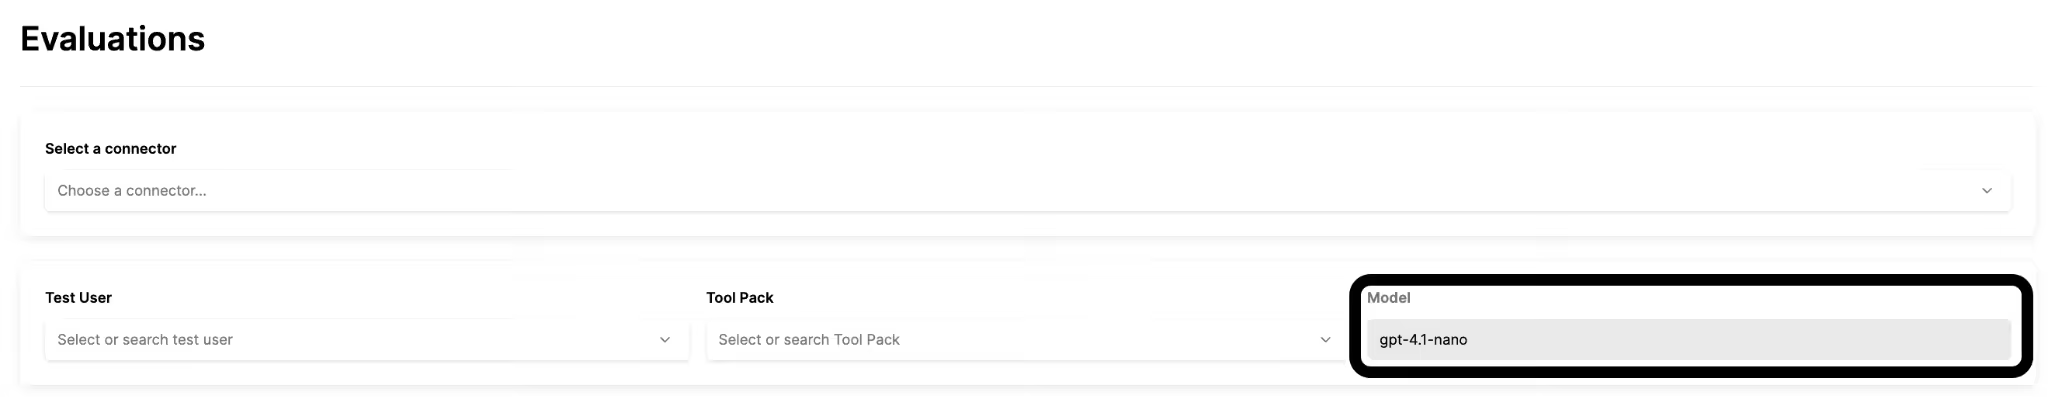
If your agents can use different LLMs depending on the customer’s plan, the prompt used, or other factors, it’s worth expanding each test to cover every model.
This also lets you isolate potential issues by LLM, enabling you to identify where certain models may underperform (e.g., invoke the wrong tools).
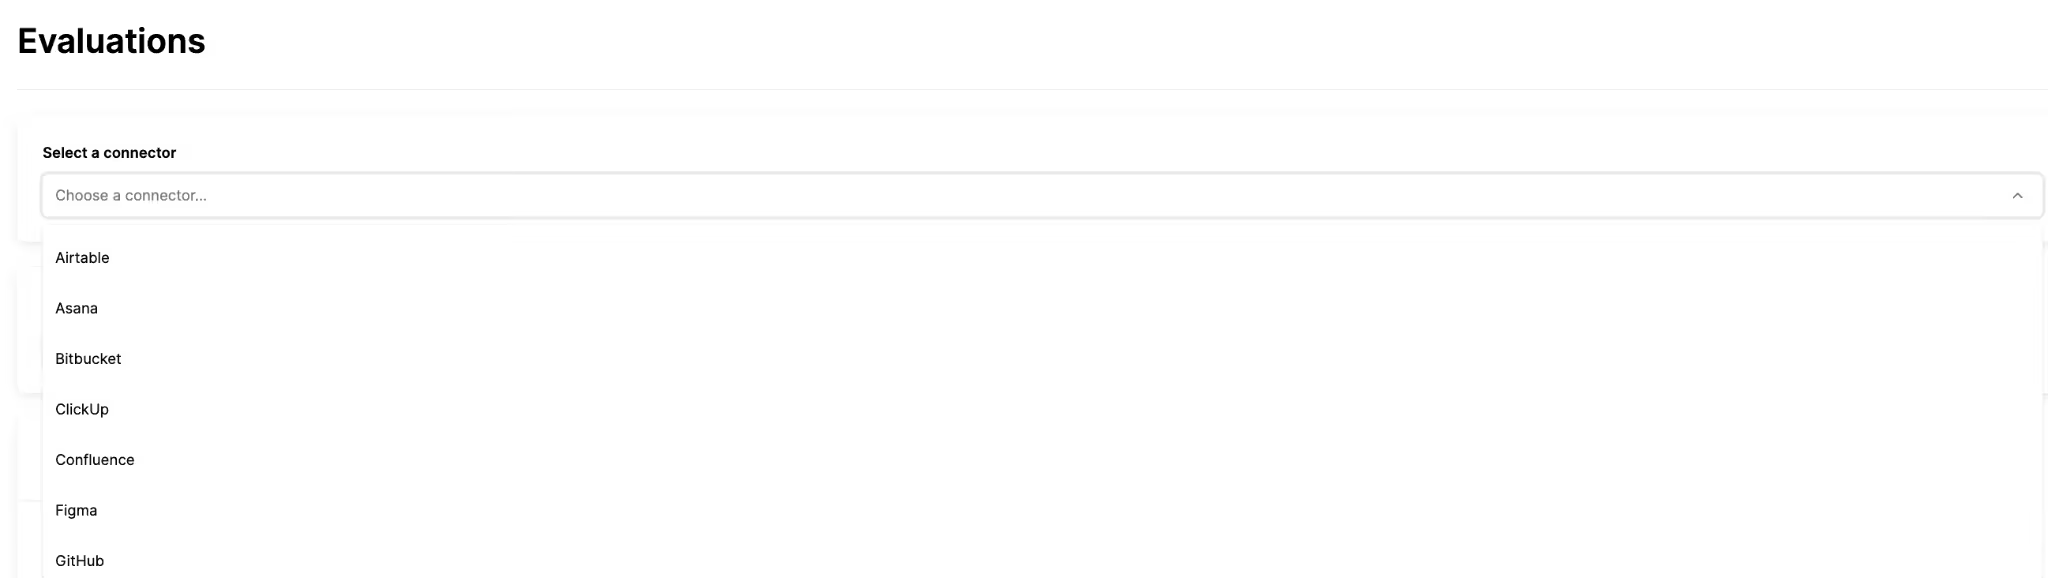
Test each MCP server you plan to use in production
Official MCP servers are often deployed with gaps, such as missing or inconsistent tool metadata and weak authentication. In many cases, they also aren’t maintained properly.
To avoid using poorly implemented and/or maintained MCP servers, or MCP connectors, you should test them against your projected prompts. This should include edge cases, malformed inputs, permission constraints, and “adversarial” scenarios (e.g., prompt injection attempts).
Related: How to test MCP servers effectively
Challenges of testing AI agents
Unfortunately, the process of testing agents can prove difficult, if not impossible, for several reasons.
- You can run endless tests . Because your AI agents handle open-ended prompts, it’s impossible to predict every scenario they’ll encounter. As a result, your tests can only provide a snapshot of your agents’ performance
- Tests aren’t fully indicative of what’ll happen in production. Since LLMs are non-deterministic, their responses can change between runs—even when everything else stays the same. This means the best testing can do is validate that your agents behave consistently enough and fail gracefully when they don’t
- It's hard to build testing infrastructure in-house. Designing, executing, and maintaining tests across multiple LLMs, prompts, connectors, and more requires deep expertise, significant engineering effort, and ongoing maintenance. And as your agents and connectors grow in number and complexity, the effort required to keep your tests comprehensive and reliable will only scale exponentially
{{this-blog-only-cta}}
AI agent testing FAQ
In case you have any more questions on testing AI agents, we’ve addressed several more below.
What are the benefits of testing AI agents?
There are several benefits worth highlighting. Here are just a few:
- Data loss prevention (DLP): With fewer, if any, data leaks, you can protect your company’s reputation, avoid the costs associated with violating data privacy regulations, and continue to provide a great user experience
- Performance optimization: You can ensure that your agents follow your authentication protocols, make the right tool calls consistently, and generate outputs that meet your expectations—all before the agents get pushed to production
- Time savings: Troubleshooting and resolving issues across your agents up front (i.e., pre-production) should lead your users to experience significantly fewer issues. Over time, this will lead to less reactive work in managing your agents across your engineering and go-to-market teams
What are some tools for testing AI agents?
The tools can vary, depending on the stage of the agent’s development.
- Testing tool calls: You can use solutions like Merge Agent Handler, Composio, or Arcade.dev to see how your agents interact with external APIs and tools.
- Testing agentic workflows: You can use tools like LangChain, CrewAI and Ema to design, simulate, and debug agent workflows
- Testing automated evals and constraints: You can use platforms like TruLens and Guardrails to assess your agents’ outputs and enforce guardrails that keep outputs within defined ethical and compliance boundaries
What are some metrics to assess AI agent performance?
Here are just a few metrics worth prioritizing:
- Hit rate: As mentioned earlier, the hit rate is the percentage of time that your agents call the right tools. It can help you determine if an MCP server's tools are exhaustive, use appropriate names, and have comprehensive descriptions
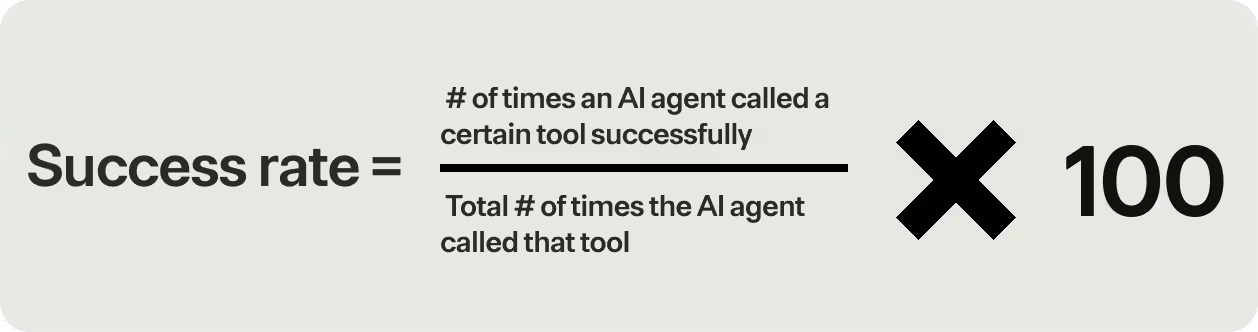
- Success rate: This is the percentage of calls to a certain tool that are successful. You can use this metric to measure whether authentication is implemented correctly, if issues are surfaced successfully (so that the agent can retry the tool call), and more
- Latency: This is how long it takes an AI agent to complete a tool call end-to-end. Relatively high latency can imply inefficiencies in the agent’s reasoning loop, network request issues, among other factors
Jon Gitlin


Test any AI agent with ease via Merge Agent Handle
Merge Agent Handler’s Evaluation Suite provides everything you’ll need to test your agents’ tool calls.


But Merge isn’t just a Unified
API product. Merge is an integration platform to also manage customer integrations. gradient text
But Merge isn’t just a Unified
API product. Merge is an integration platform to also manage customer integrations. gradient text
But Merge isn’t just a Unified
API product. Merge is an integration platform to also manage customer integrations. gradient text
But Merge isn’t just a Unified
API product. Merge is an integration platform to also manage customer integrations. gradient text