

Table of contents

Claude Sonnet 5 vs GPT-5.6 Terra: how they compare on coding

Jon Gitlin
Claude Sonnet 5 and GPT-5.6 Terra can handle the work developers lean on a model for: scaffolding a service and its tests, writing an integration against a third-party API, turning a schema into typed models, or building a full UI in one pass.
The gap shows up in how fast they generate outputs, how many tokens they burn, and how finished the output looks.
To help you compare the two for your coding workflows, we'll compare Claude Sonnet 5 and GPT-5.6 Terra through an identical build test.
Overview on Claude Sonnet 5 and GPT-5.6 Terra
Claude Sonnet 5 is Anthropic's proprietary workhorse model, and was released at the end of June, 2026. It pairs a 1,000,000-token context window with strong coding and agentic performance. It's priced at $2 per million input tokens and $10 per million output.
GPT-5.6 Terra is the mid tier of OpenAI's GPT-5.6 family (which also ships a lighter Luna tier and a flagship Sol tier), and was released in July, 2026. It carries a 1,050,000-token context window and sits just below Sonnet 5 on price, at $1.875 per million input tokens and $11.25 per million output.
Related: How GPT-5.6 Sol compares to Claude Fable 5
Claude Sonnet 5 vs GPT-5.6 Terra (based on our research)
Artificial Analysis hasn't published Coding Agent Index scores for Claude Sonnet 5 yet, so there's no clean third-party head-to-head to point at.
Rather than lean on a one-sided benchmark, we ran our own build test:
1. We wrote one identical prompt for both models: "Build the marketing homepage for a fictional company, Fennmark, a procurement management platform. Build it as a single self-contained HTML file with a dynamic hero section, a nav bar, features, social proof, a pricing or CTA section, and a footer."
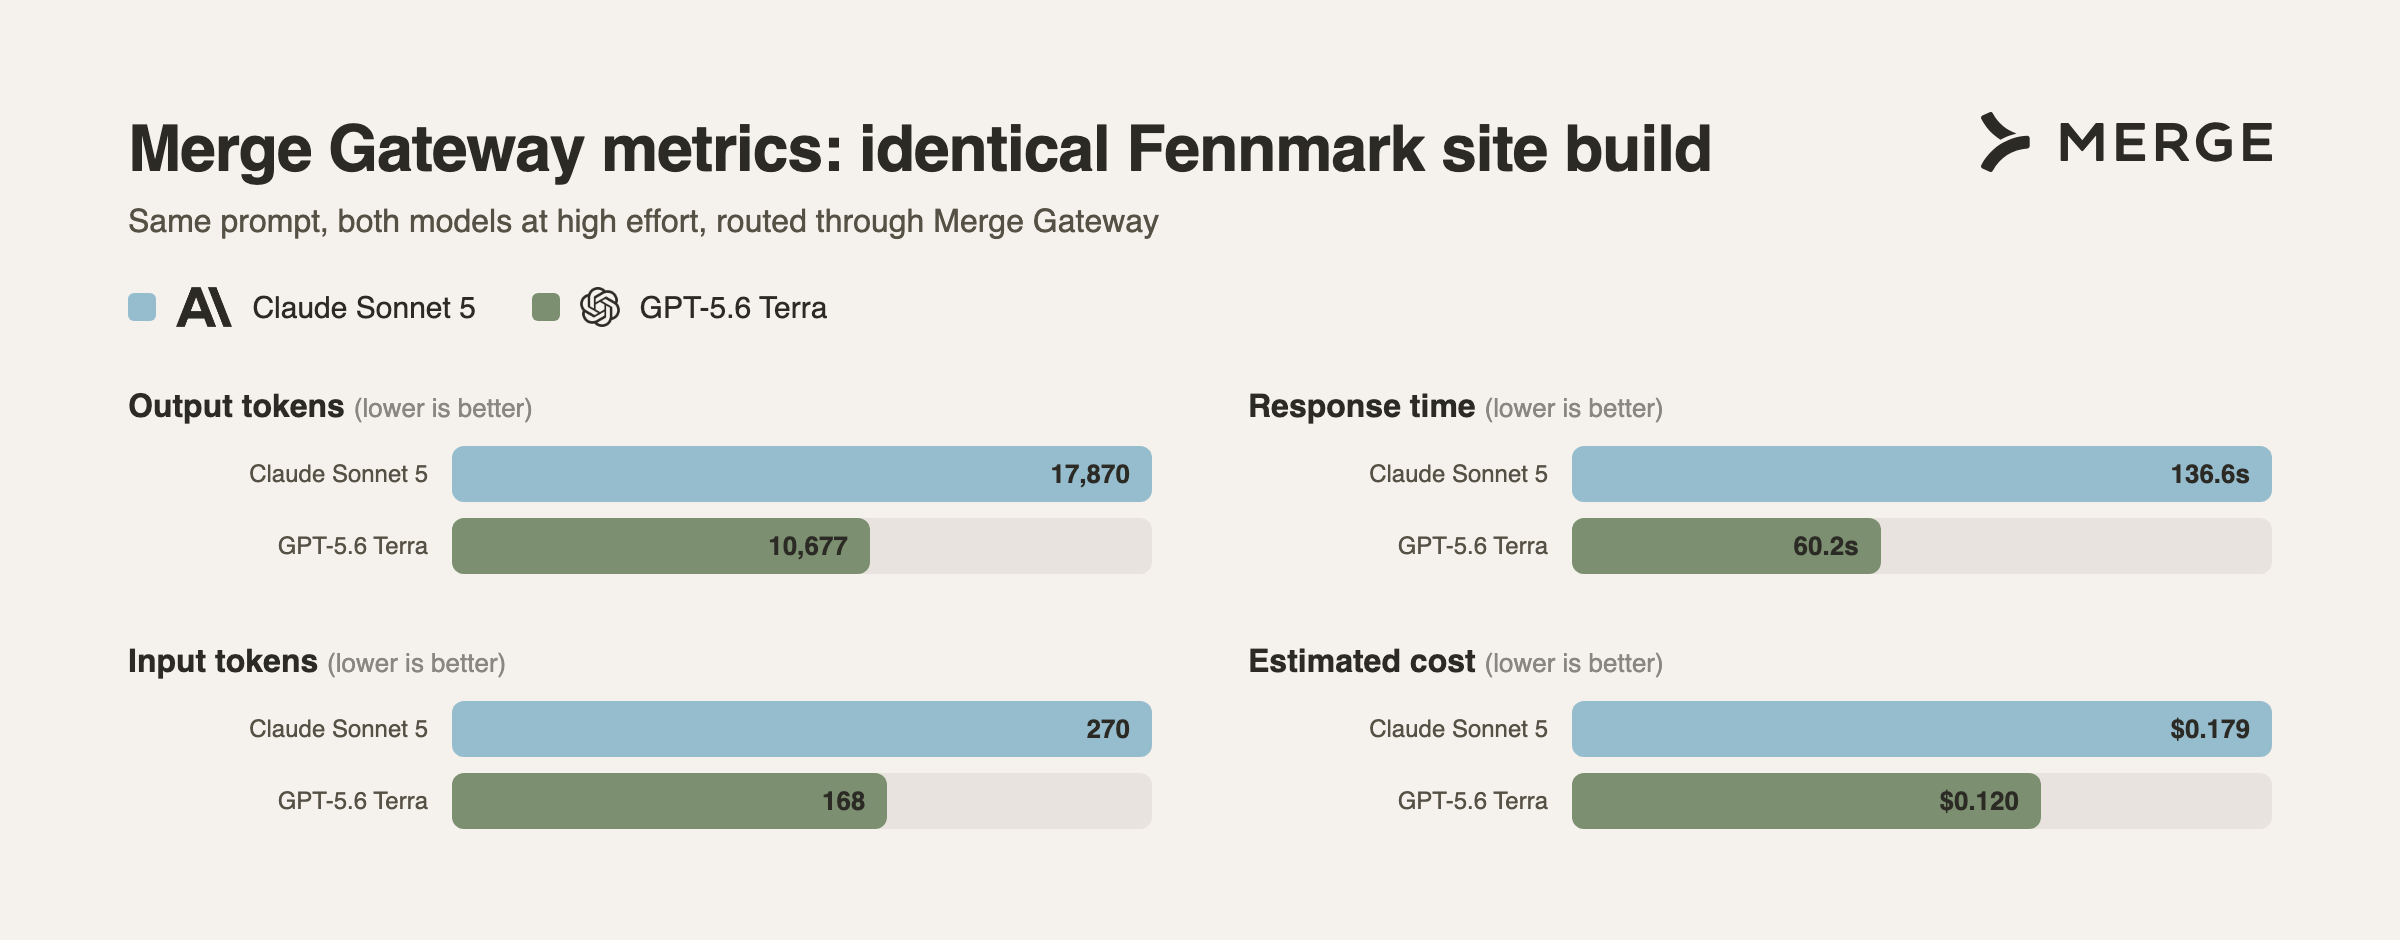
2. We routed that same prompt to each model through Merge Gateway at high reasoning effort, one generation each, and recorded the input tokens, output tokens, total response time, and estimated cost Gateway reported.
3. Then we rendered both results and looked at how the sites actually turned out.
On the numbers, GPT-5.6 Terra was the clear winner. It finished in 60.2 seconds to Sonnet 5's 136.6, used fewer output tokens (10,677 vs 17,870), and cost less to generate the same page ($0.120 vs $0.179, about 33% cheaper).
The question is whether that efficiency cost anything in quality.
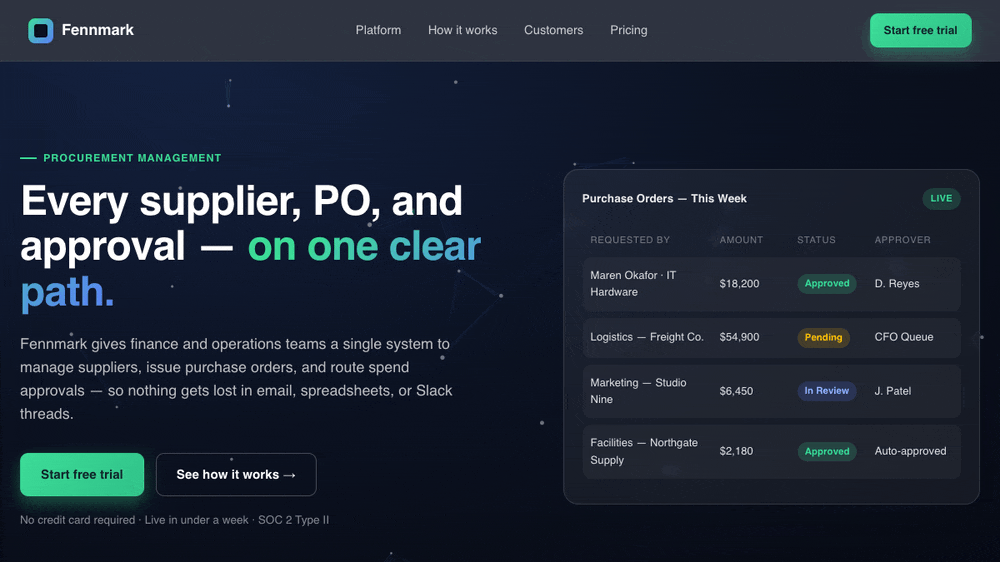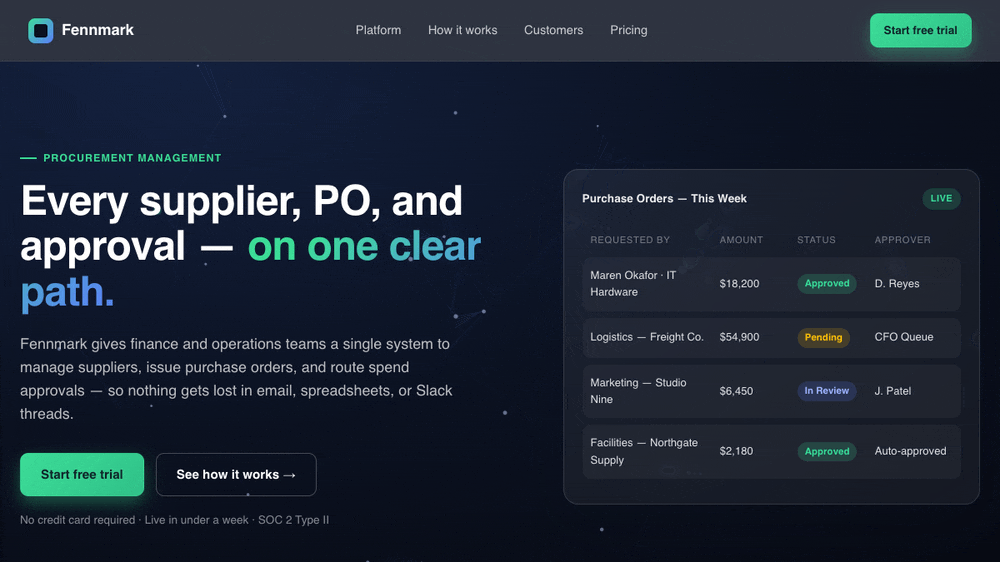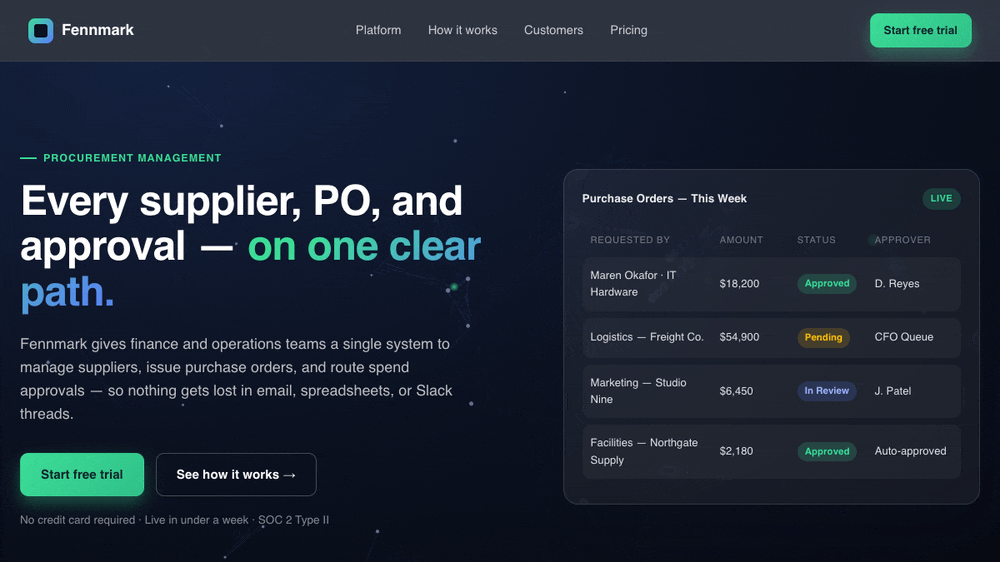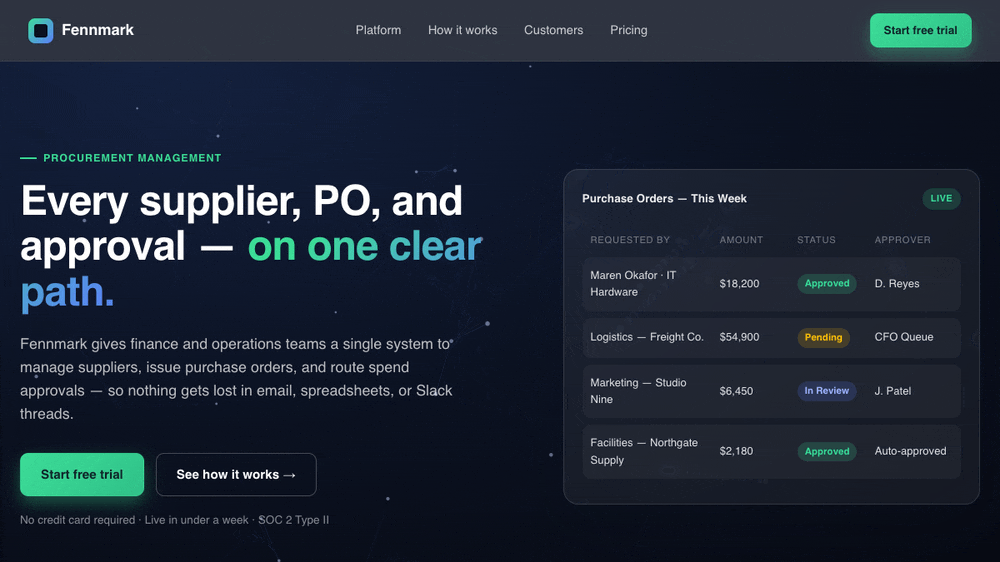
Here's Claude Sonnet 5's hero:
And GPT-5.6 Terra's:

The two builds are both genuinely strong and remarkably close.
Both nailed the hard part: a real animated hero (a moving constellation of connected dots, not a static image), and both wrote sharp, Fennmark-specific copy with a convincing product mockup.
Sonnet 5 rendered a live "Purchase Orders" table, while Terra rendered a fuller in-app view with a sidebar, stat cards, and a floating approval toast. Terra pushed a bit further on polish (an announcement bar, a 4.9/5 rating, and the richer app mockup) and a slightly fuller nav, while Sonnet 5 built one more page section and leaned on a bold dark theme against Terra's lighter one.
Both fell short in the same areas. Neither adapts to a phone screen, keeping the full desktop nav and running off the edge instead of resizing.
On aggregate, GPT-5.6 Terra is the clear winner. It matched Sonnet 5's quality while running more than twice as fast and about a third cheaper.
Related: How to decide between GLM-5.2 and Claude Sonnet 5 for your coding workflows
Final thoughts
Based on our build, GPT-5.6 Terra is the pick when speed and cost matter most (interactive coding where latency is felt, high-volume generation, cost-sensitive workloads), while Claude Sonnet 5 stays a top choice for teams that value Anthropic's coding pedigree (agentic and multi-step tool use, complex refactors, long-context work).
To reap the benefits of each model (and any other), you can use Merge Gateway to route each request to the model that best fits your requirements.
Merge Gateway lets you:
- Reach every major model, including Claude Sonnet 5 and GPT-5.6 Terra, through one API and one integration
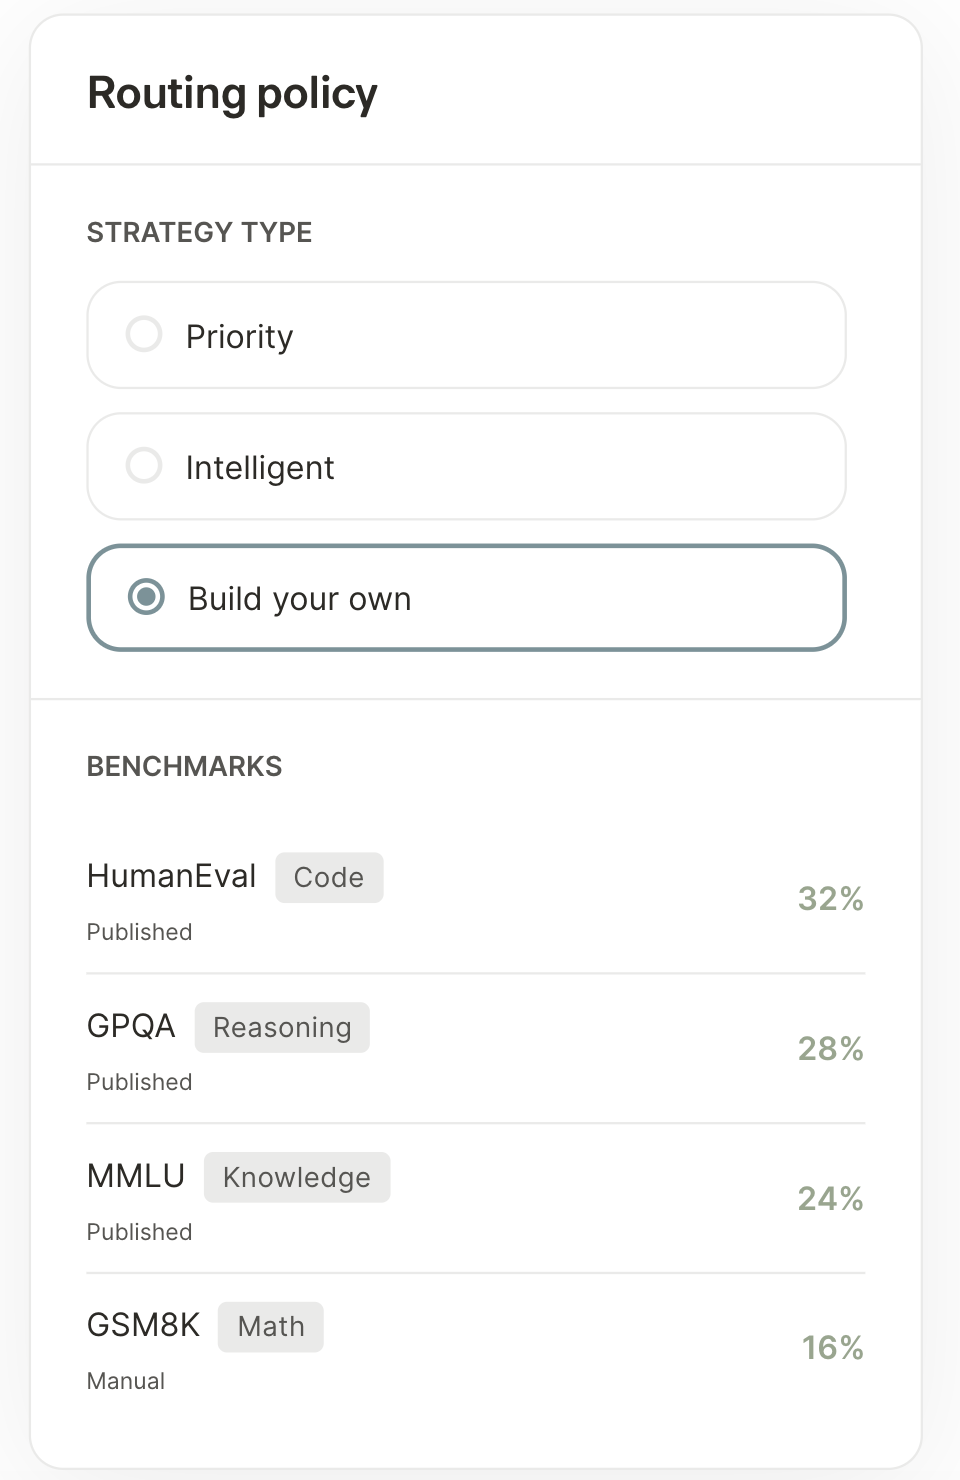
- Use Build Your Own Router (BYOR) to route on your own benchmark or eval scores, not just cost or latency
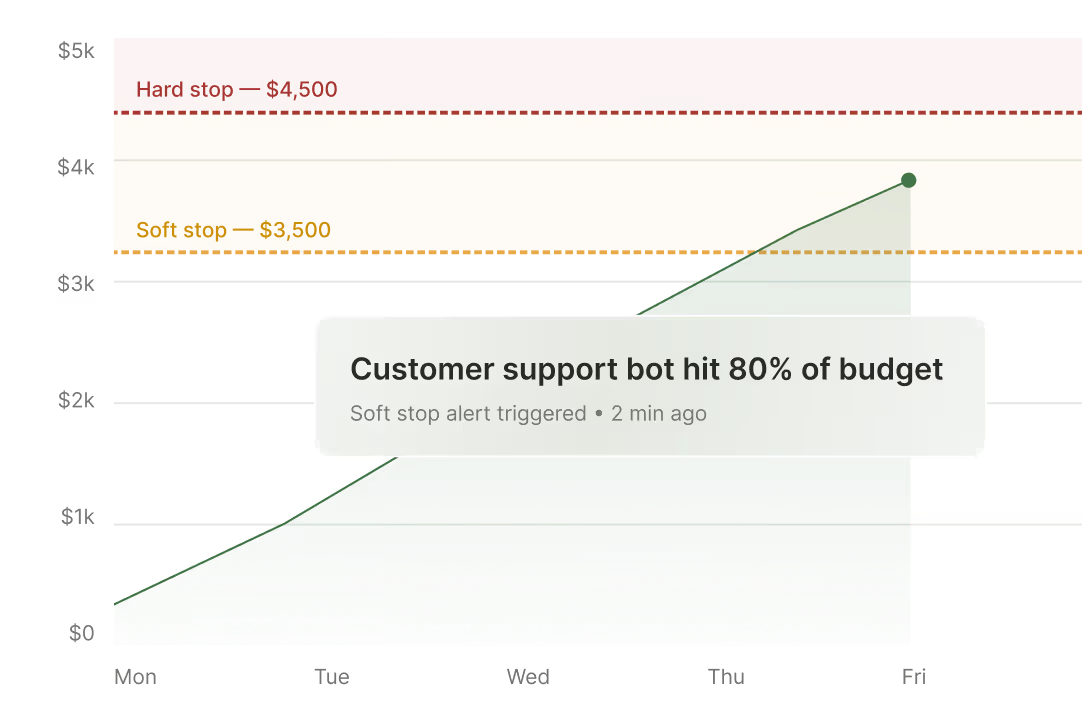
- Set budgets, spend limits, and per-project cost visibility so a high-volume workload can't quietly blow past your plan
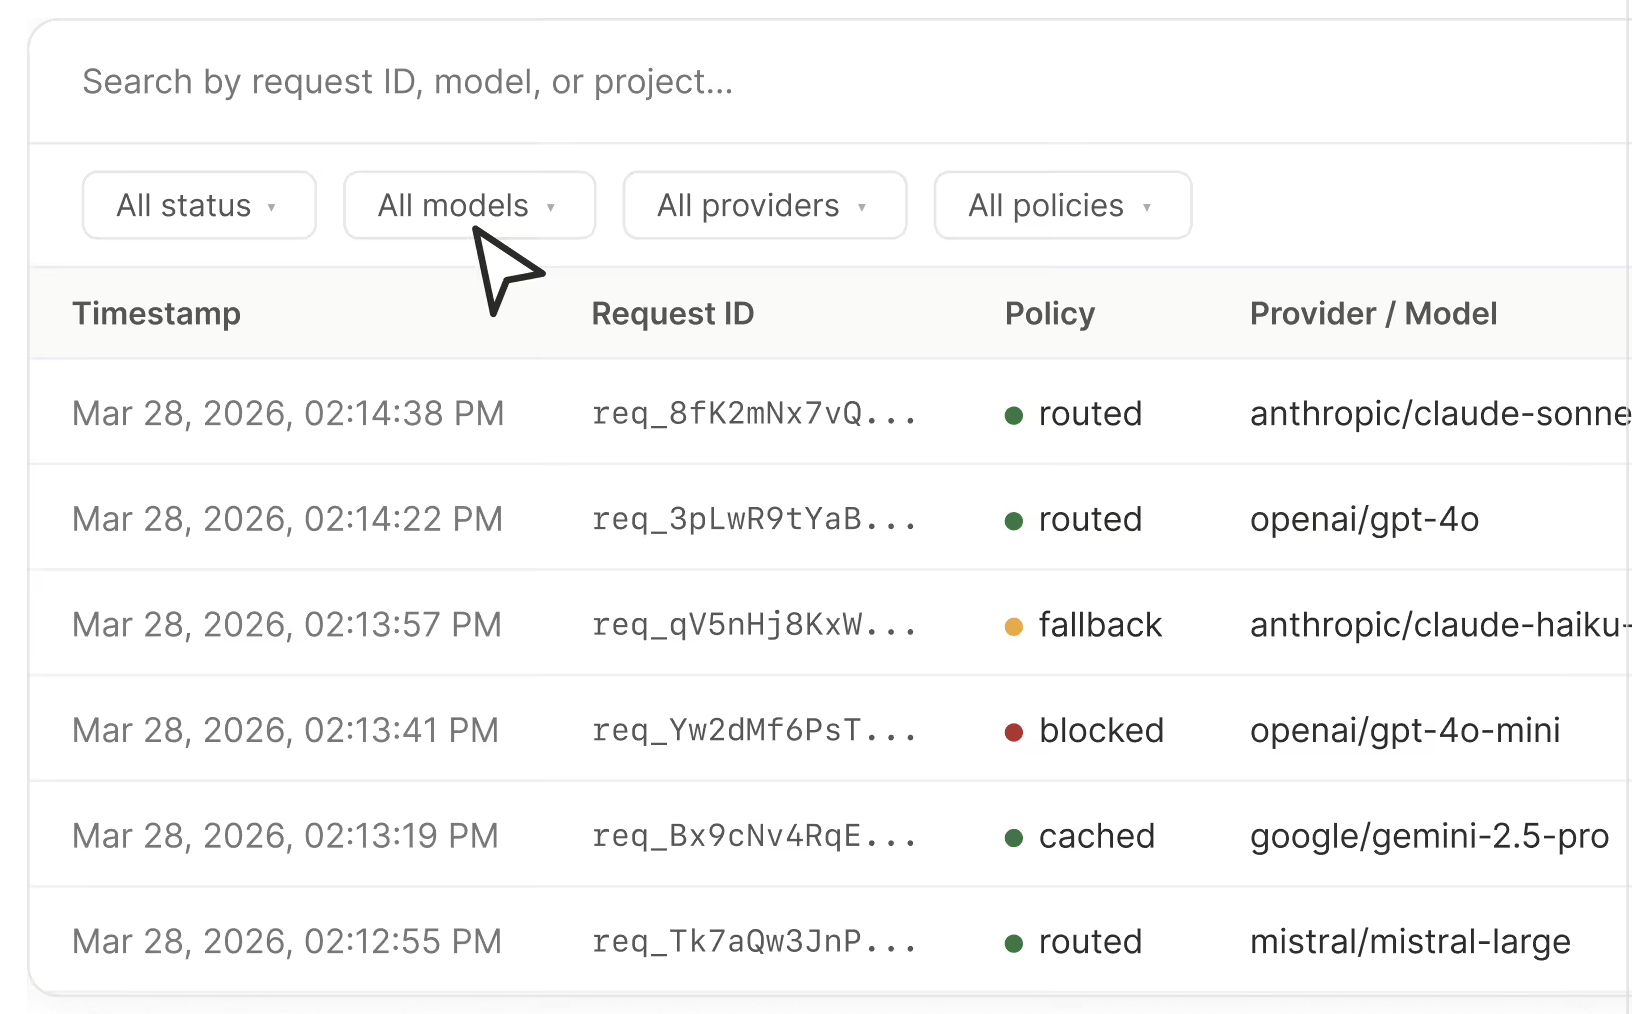
- Get per-request logging and tracing across every model and provider
- Fall back automatically when a provider errors or rate-limits, so a single outage doesn't take your feature down
{{this-blog-only-cta}}
Claude Sonnet 5 vs GPT-5.6 Terra FAQ
In case you have any more questions on either model, we've addressed several more below.
What is the context window for Claude Sonnet 5 and GPT-5.6 Terra?
Claude Sonnet 5 has a 1,000,000-token context window with a 128,000-token maximum output, per Anthropic's model documentation. GPT-5.6 Terra has a slightly larger 1,050,000-token context window, also with a 128,000-token maximum output, per OpenAI's model documentation.
The two are effectively matched here.
Both windows are large enough to hold a substantial codebase, long specs, and multi-file context in a single request, and both can return equally long single responses.
What other models should I consider besides Claude Sonnet 5 and GPT-5.6 Terra?
A few others are worth evaluating depending on your priorities.
- Claude Opus 4.8: ideal when you want the strongest reasoning and will accept higher cost and latency (e.g., large multi-file refactors)
- Gemini 3 Pro: best when a task means reasoning over a whole repo or a long spec in one pass before editing
- DeepSeek V4 Pro: an open-weight model that's a good fit for high-volume or batch code generation where per-token price matters most
What are the most common coding use cases for Claude Sonnet 5 and GPT-5.6 Terra?
Claude Sonnet 5 fits agentic and quality-first work. This includes multi-step tool use, complex refactors and debugging, and long-context tasks where its context window and Anthropic's coding pedigree pay off.
GPT-5.6 Terra fits speed- and cost-sensitive work, such as interactive coding assistants where response time is felt, high-volume code generation, and one-shot builds like the site test above.
Jon Gitlin


Start routing requests to any model through Merge Gateway
Try Merge Gateway for free and route your next coding task to the model that fits it best.


But Merge isn’t just a Unified
API product. Merge is an integration platform to also manage customer integrations. gradient text
But Merge isn’t just a Unified
API product. Merge is an integration platform to also manage customer integrations. gradient text
But Merge isn’t just a Unified
API product. Merge is an integration platform to also manage customer integrations. gradient text
But Merge isn’t just a Unified
API product. Merge is an integration platform to also manage customer integrations. gradient text