Merge for Private Equity
Improve margins across your portfolio
Up to ~20% reduction* in LLM spend through a single line of code
*Based on average savings across customers using Merge Gateway’s intelligent model routing.
Trusted by teams building the next generation of AI products
“With Merge Agent Handler, we can bring a broader set of data connectors to our users faster and constantly expand what our customers can do with Perplexity Enterprise Pro.”
Frank te Pas
Head of Enterprise Product at Perplexity

Case study

“Before launching our HRIS integrations, a few team members at Merge came on-site to train our customer-facing teams on marketing, selling and supporting the integrations. This took additional work off of my team’s plate and has helped us take the integrations to market more efficiently.”
Alex Giddens
Senior Product Manager
Case study
“Working with Merge’s Unified API and beautiful React component took less than a sprint to integrate, test, and release.”
Daniel Marashlian
Co-founder & CTO
Case study
“Merge’s post-sales team is truly amazing. They’re fast, responsive, and deeply knowledgeable of HRIS integrations and our use case.”
Katie Harmon
Senior Director of Channels
Problem
AI is becoming a top 3 cost, and it’s almost always unoptimized
Every portfolio company independently rebuilds AI infrastructure from scratch. The inefficiency compounds across the portfolio.

Defaults to the most expensive model
Engineering hardcodes one model across all use cases.

AI spend can't be forecasted
Provider invoices don’t break out spend by product, team, or customer. Can’t set limits until after costs spike.

Every portco rebuilds the same infrastructure
Every portco spends months building the same cost controls from scratch. No shared leverage, no compounding value.

One line of code.
Deploy once.
No excuses.
Your portco swaps one URL. Everything else stays the same, including code, SDKs, prompts, product.
Before
base_url = "https://api.openai.com/v1"

After
base_url = "https://gateway.merge.dev/v1"
Optimization happens automatically
Every request is routed to the lowest-cost model that meets quality requirements.
Savings show up immediately
Reduce LLM spend from the first invoice. No engineering work. No rollout risk.
Standardize across every portco
Same integration. Same playbook. No product changes required.
See the math
Turn AI cost optimization into a value creation lever
This is not a one-time optimization.
It’s a playbook you apply across every company.
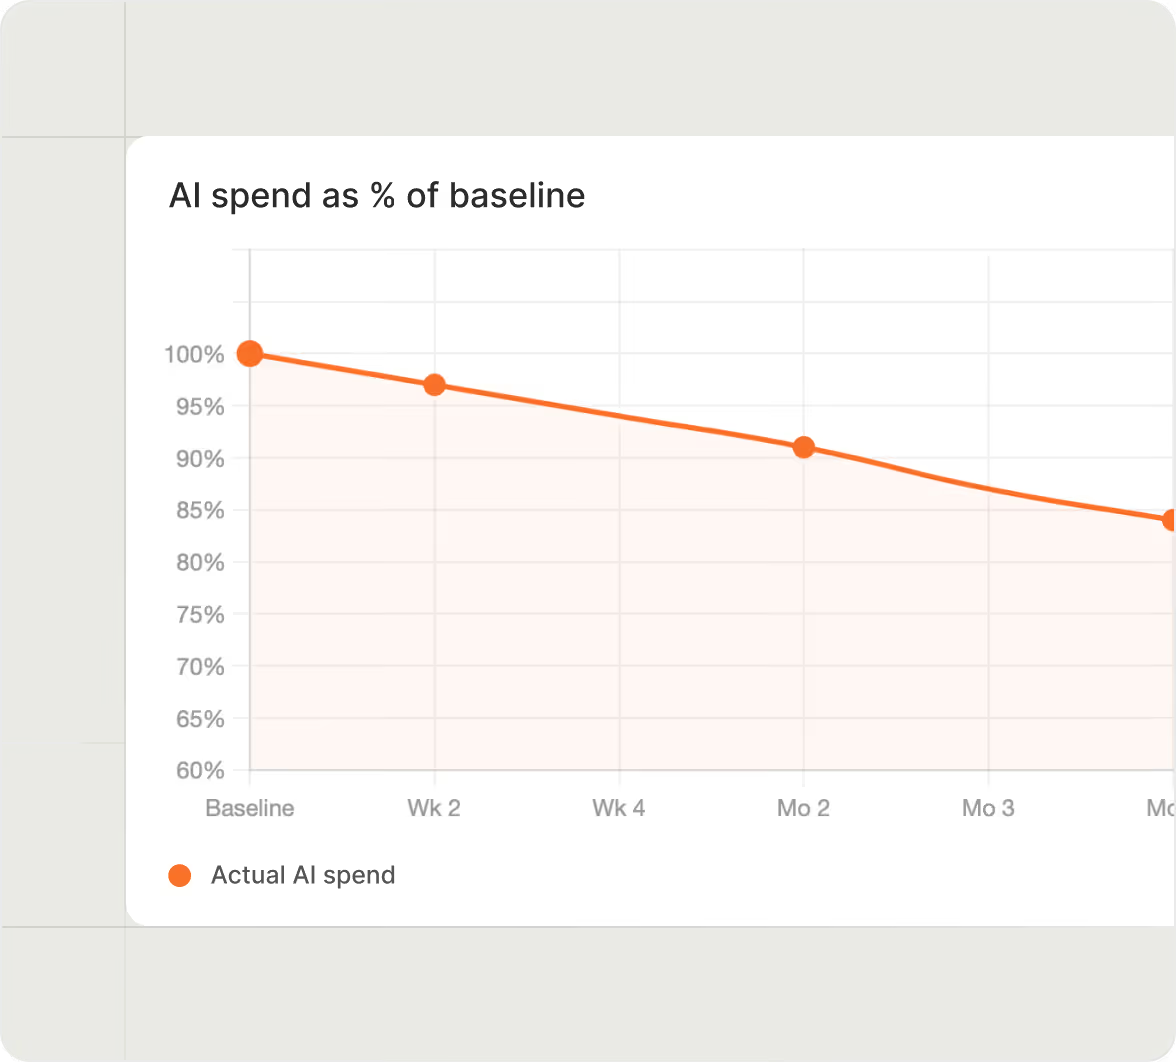

Example
How a $1M/year AI spend becomes $800K
A mid-market SaaS company spending $1M/year on LLM inference. Here’s what happens after a 1-minute integration.
Step 1
You find the waste in diligence
Engineering hardcoded every AI call to the same model, paying premium rates for simple tasks that don't need them

*Illustrative: 2.8M requests/month at 1,000 tokens average (input only), priced at GPT-4's published rate of $30/million tokens
Step 2
Portco swaps one line. Merge does the rest.
Each task gets routed to the cheapest model that maintains quality.
| Task type | % of calls | Routing change | Cost /M tokens |
|---|---|---|---|
| Simple tasks (tagging, extraction) | 50% | GPT-5.5 → GPT-5.4 nano | $0.80/M |
| Mid-complexity (chat, summaries) | 30% | GPT-5.5 → Sonnet 4.7 | $0.30/M |
| Complex reasoning | 20% | GPT-5.5 → GPT-5.5 (no change) | $30/M |
Step 3
Margin expansion from month one
No new headcount. No engineering project. Pure margin improvement from month one.
* Based on $1M annual AI spend per portco with ~20% cost reduction from intelligent routing. Actual savings vary by workload.
Portfolio rollout model
The more companies you onboard, the more leverage you gain
Merge charges LLM cost plus a small margin. No platform fees.
No per-seat charges. The margin shrinks as you scale.

$1,000 free credit per portfolio company*
Portcos | Merge margin | Est. annual savings | |
|---|---|---|---|
Portcos | 1–3 | 5.0% | $320k |
Growth | 4–7 | 4.7% | $893k |
Scale | 8-14 | 4.4% | $1.81M |
Portfolio | 15-24 | 4.2% | $3.24M |
Enterprise | 25+ | 4.0% | $4.2M+ |
How we estimated savings:
Assumes $1M annual AI spend per portfolio company with ~20% gross cost reduction from intelligent model routing. Merge margin applied to post-routing LLM cost. Portfolio savings use midpoint of each tier’s range. Actual savings vary by workload. Enterprise shown for 25 companies.
* Offer available to new Merge Gateway customers that are majority-owned, controlled, or actively backed by a private equity firm, as verified by Merge. To earn the credit, customer must incur at least $500 in eligible Gateway usage in each of two consecutive billing months ($1,000+ total qualifying spend).

Cody Therrien
Founding AI Engineer, Peec AI
See how much margin you can unlock across your portfolio
Start with one portco. See results in the first month. Scale from there.